A Complete Technical Explanation: From Tokens to Predictions

Abstract
This paper provides a complete, ground-up explanation of how Large Language Models (LLMs) work. A central section walks through the entire forward pass with concrete numbers: embedding lookup, Query/Key/Value matrices, the dot-product score matrix, softmax weights, weighted Value sums, layer-by-layer refinement, and the final word prediction. It explains how backpropagation adjusts every matrix in response to prediction errors. It also covers fine-tuning and RLHF in detail. The paper concludes by applying this understanding to explain precisely why LLMs fail at constraint satisfaction.
Note: Throughout this paper, vector dimensions and vocabulary sizes are illustrative examples. Different models use different values.
1. Words as Vectors
1.1 The Core Idea
The fundamental insight behind modern language models is that words can be represented as points in a high-dimensional geometric space. Rather than treating words as discrete, unrelated symbols, we map each word to a vector — a list of numbers — such that words with similar meanings end up close together in that space.
The geometry of the space encodes meaning. Proximity means similarity. Direction encodes relationships.
The famous demonstration of this is analogy arithmetic. In a well-trained embedding space:
king − man + woman ≈ queen
This is not hand-coded. It emerges from training. The model discovered a consistent geometric relationship between gender-related concepts. The vector from ‘man’ to ‘woman’ points in the same direction as the vector from ‘king’ to ‘queen.’
1.2 Tokens
LLMs operate on tokens — chunks of text produced by a tokenizer. A token might be a full word, a subword, or punctuation. The dominant approach is Byte Pair Encoding (BPE), which iteratively merges frequent adjacent character pairs. Vocabulary size varies from roughly 30,000 to over 100,000 tokens depending on the model.
2. The Embedding Matrix
2.1 Structure
The embedding matrix is a lookup table with one row per vocabulary token. Each row is a vector of D numbers — the embedding dimension, which might be 256, 768, 4096, or more. When a token is fed into the model, its integer ID looks up the corresponding row. That row is the token’s initial static vector.
At this stage, every token has exactly one vector regardless of context. ‘Bank’ near ‘river’ and ‘bank’ near ‘money’ produce the same initial vector. The attention mechanism, described next, will resolve this.
2.2 How the Embedding Matrix Is Built
The embedding matrix starts as random numbers and is shaped by training via the distributional hypothesis: words that appear in similar contexts tend to have similar meanings. ‘Cat’ and ‘dog’ both appear near ‘pet’, ‘food’, ‘fur’. They almost never appear near ‘quarterly earnings’. Backpropagation sends similar gradient signals to similar-context tokens over billions of training steps, causing their rows to drift toward each other in the D-dimensional space.
3. The Attention Mechanism: Overview
Consider: ‘The animal didn’t cross the street because it was too tired.’ What does ‘it’ refer to? A human reader knows immediately — ‘animal.’ But resolving this requires looking back across several tokens. The attention mechanism formalizes this: for each token, determine which other tokens are most relevant, and incorporate their information into a richer representation.
The mechanism uses three learned matrices per layer: the Query matrix (WQ), Key matrix (WK), and Value matrix (WV), each D×D. Each token’s vector is multiplied by all three:
Query_i = embedding_i × WQ
Key_i = embedding_i × WK
Value_i = embedding_i × WV
Query is what a token is looking for. Key is what it offers. Value is its information payload. The following section walks through this computation in full with concrete numbers.
4. The Multi-Layer Transformer
4.1 Stacking Attention Layers
One round of attention produces contextual vectors that are richer than the original embeddings. But the model does not stop there. The output vectors from the first attention layer become the input to a second attention layer — with its own independent set of Q, K, V matrices — which produces further refined vectors. This stacks repeatedly to form the full transformer.
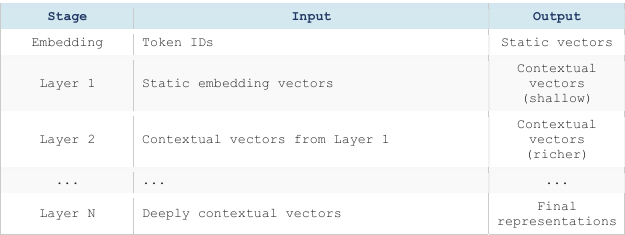
Note: N is the number of layers, a design choice. GPT-2 (small) uses 12 layers. GPT-3 uses 96. Larger models generally have more layers.
4.2 What Each Layer Learns
Each layer has its own Q, K, V matrices, learned independently during training. Research has shown that different layers tend to specialize in different kinds of linguistic knowledge, though this division of labor was never explicitly programmed — it emerged from the training objective.
- Early layers: Syntactic structure. Subject-verb agreement. Part-of-speech. Local dependencies between adjacent or nearby words.
- Middle layers: Semantic content. Word sense disambiguation. ‘Bank’ near ‘river’ versus ‘bank’ near ‘money’ begins to diverge here. Phrase-level meaning.
- Later layers: High-level abstractions. Discourse structure. Long-range coreference. Tone and intent.
Each additional layer allows the model to form more abstract and powerful representations. The depth of the network is one of the primary sources of model capability.
4.3 How a Token’s Representation Evolves
The following diagrams trace the token ‘bank’ as its vector evolves through successive attention layers, and contrast two different sentential contexts — showing how the same initial vector can arrive at completely different final positions depending on surrounding words.
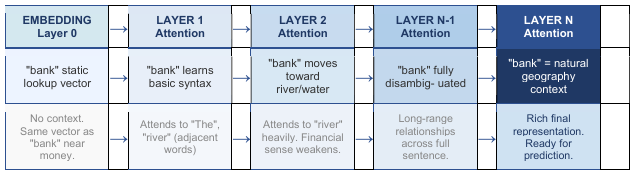
Figure 1. Evolution of the token ‘bank’ through attention layers in the sentence ‘The river bank was steep.’ Each layer refines the representation using different Q, K, V matrices. By the final layer, the geometric position of ‘bank’ reflects the river context specifically, not the financial meaning.
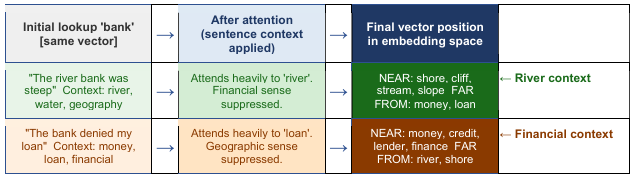
Figure 2. The same initial ‘bank’ vector diverges into two completely different final positions depending on sentence context. This is the core achievement of contextual embeddings built by attention.
4.4 Why Attention Is the Important Part
The embedding matrix provides starting positions. Attention is what makes those positions meaningful. Before the 2017 paper ‘Attention Is All You Need’ (Vaswani et al.), the dominant approach used recurrent neural networks (RNNs) that processed tokens sequentially, passing a hidden state from left to right. Information had to travel through many sequential steps and could fade over long distances. Attention allows every token to directly attend to every other token regardless of distance, with no information decay, and is fully parallelizable across GPU hardware.
The embedding space is the primary artifact of training. Attention is the primary mechanism that builds it. Good embeddings — rich, contextually appropriate representations — are where most of the intelligence lives. The final prediction step, given a good embedding, is relatively mechanical.
5. The Complete Forward Pass: A Worked Example
This section walks through the entire computation from input tokens to word prediction, using concrete numbers at every step. We use a simplified example with small vectors to make the arithmetic transparent. The same process runs identically in real models with much larger dimensions.
5.1 Setup
We use three tokens from the sentence ‘The cat sat on the mat’:
- Tokens: ‘The’, ‘cat’, ‘sat’
- Embedding dimension D = 3 (real models use hundreds or thousands)
- Vocabulary V = 5 words: ‘the’, ‘cat’, ‘sat’, ‘on’, ‘mat’
- Two attention layers (real models use 12 to 96)
Note: The numbers below are computed from actual matrix multiplications — they are not invented for illustration. All arithmetic can be verified.
5.2 Step 1: Embedding Lookup
Each token is looked up in the embedding matrix to retrieve its initial D-dimensional vector. These are static — no context yet. Both instances of ‘the’ in any sentence would return the same vector at this stage.
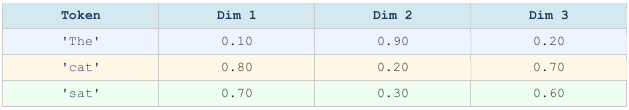
Table 1. Embedding vectors for the three tokens. These are the rows looked up from the embedding matrix. D=3 here for clarity; real models use much larger D.
5.3 Step 2: Computing Query and Key Vectors
Each embedding vector is multiplied by the Query matrix (WQ) and the Key matrix (WK) to produce a Query vector and a Key vector for every token. These are different projections of the same original vector — WQ pulls out ‘what am I looking for’, WK pulls out ‘what do I offer.’
The matrices WQ and WK are 3×3 and are learned during training. After multiplying:
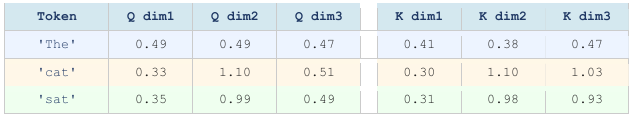
Table 2. Query (left) and Key (right) vectors for Layer 1, computed by multiplying each embedding vector by WQ and WK respectively.
Notice: ‘cat’ and ‘sat’ have large values in dimensions 2 and 3 of both their Query and Key vectors. This means they will produce high dot products with each other — the matrices have learned that nouns and verbs are relevant to each other, even before any context-aware computation has run.
5.4 Step 3: The Score Matrix
For every pair of tokens, we compute the dot product of one token’s Query vector with the other’s Key vector. This gives a score measuring how much the first token should attend to the second. For 3 tokens this produces a 3×3 matrix of scores. The dot product is: multiply corresponding elements, sum them all up. For example, the score for ‘cat’ attending to ‘sat’ is:
Q_cat · K_sat = (0.33×0.31) + (1.10×0.98) + (0.51×0.93)
= 0.10 + 1.08 + 0.47 = 1.65
Scaled by 1/√3 ≈ 0.577: 1.65 × 0.577 = 0.95
We divide by √D (here √3 ≈ 1.73) to prevent scores from becoming very large in high dimensions, which would destabilize softmax. Computing all 9 dot products gives:
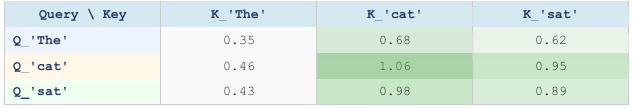
Table 3. Score matrix (scaled dot products). Each entry shows how much the row token attends to the column token. Darker green = higher score = stronger attention. Notice ‘cat’ attends strongly to ‘cat’ (1.06) and ‘sat’ (0.95), much more than to ‘The’ (0.46).
This pattern makes sense: ‘cat’ and ‘sat’ are the semantically rich content words. ‘The’ is a function word with little independent meaning. The Q-K matrices have learned, through training, to give high scores to content-word pairs.
5.5 Step 4: Softmax — Scores to Weights
Each row of the score matrix is passed through softmax independently. Softmax converts a row of raw scores into a row of weights that sum to 1. High scores become high weights; low scores become near-zero weights.
For the ‘cat’ row [0.46, 1.06, 0.95]:
exp(0.46) = 1.58, exp(1.06) = 2.89, exp(0.95) = 2.59
sum = 7.06
weights = [1.58/7.06, 2.89/7.06, 2.59/7.06] = [0.22, 0.41, 0.37]
Doing this for all three rows:
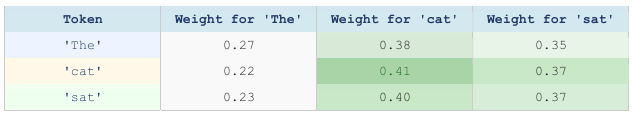
Table 4. Attention weights after softmax. Each row sums to 1.00. ‘cat’ draws 41% of its information from ‘cat’ and 37% from ‘sat’, with only 22% from ‘The’. ‘The’ draws more evenly, as it is a function word dependent on its context for meaning.
These weights answer the question: when building a new, contextually-aware representation for each token, how much should each neighbouring token contribute? The weights are different for every token, and they change with every different sentence. This is attention.
5.6 Step 5: Value Vectors
Each token also has a Value vector, computed by multiplying its embedding by the Value matrix (WV). The Value vector is the actual information payload the token will contribute when selected. Unlike Query and Key which are used only for computing attention weights, Value carries the content.
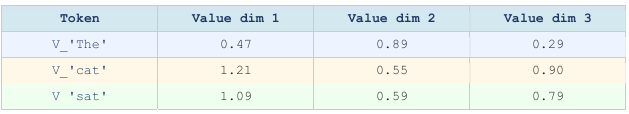
Table 5. Value vectors for all three tokens in Layer 1. These are computed by multiplying each embedding by WV.
5.7 Step 6: The Weighted Sum — New Contextual Vectors
Now we combine everything. For each token, we take its row of attention weights and use them to compute a weighted average of all three Value vectors. The result is a new vector for that token — its contextual representation.
Let us compute this explicitly for the token ‘sat’, which has attention weights [0.23, 0.40, 0.37]:
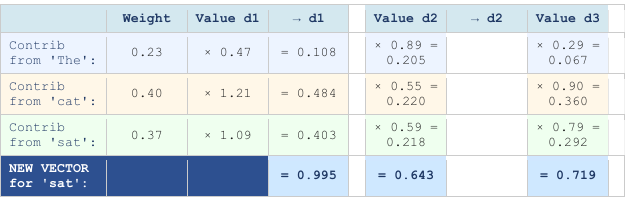
Table 6. Weighted sum computation for token ‘sat’. Each dimension is computed independently by multiplying attention weights by Value vectors and summing. The new vector [0.995, 0.643, 0.719] is ‘sat’s contextual representation after Layer 1.
Compare the original embedding of ‘sat’ [0.70, 0.30, 0.60] with its new contextual vector [1.00, 0.64, 0.72]. The vector has shifted considerably. It now carries blended information from all three tokens, weighted by how relevant each was. Because ‘cat’ contributed 40%, the new ‘sat’ vector has absorbed substantial information from the animal noun — the subject performing the action. The same weighted-sum computation runs for ‘The’ and ‘cat’, each using their own row of attention weights. The result is three new vectors:
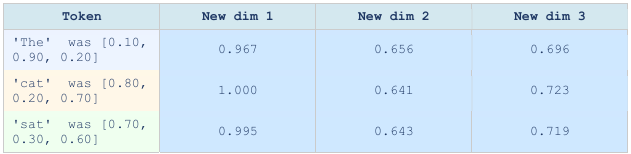
Table 7. Layer 1 output: new contextual vectors for all three tokens (blue). Compare with their original embedding vectors (shown in the Token column). All three have shifted substantially. Notice that the three output vectors are now more similar to each other than the inputs were — they have blended information from the same pool of three Value vectors, weighted differently.
This is the fundamental operation of one attention layer: three static, context-free lookup vectors go in; three enriched, contextually-aware vectors come out. Each output vector is a blend of information from all input tokens, weighted by relevance. ‘The’ has been transformed from a generic article [0.10, 0.90, 0.20] into a representation [0.97, 0.66, 0.70] that reflects the specific sentence it appeared in.
5.8 Layer 2: The Same Process with New Matrices
The three output vectors from Layer 1 now become the inputs to Layer 2. The process is identical — multiply by new WQ², WK², WV² matrices, compute dot products, softmax, weighted sum. But two things are different:
- The input vectors are now contextually enriched, not raw embeddings. Layer 2 is operating on representations that already encode relationships from Layer 1.
- The matrices WQ², WK², WV² are independent from Layer 1’s matrices. They were learned separately. They can therefore detect different kinds of relationships.
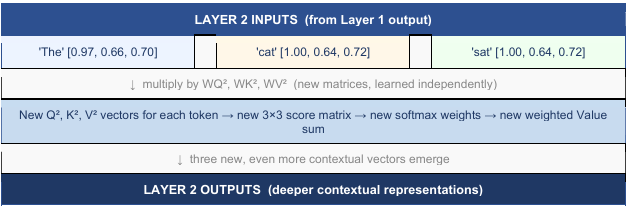
Figure 3. Layer 2 takes the output of Layer 1 as its input. The process is identical but uses different matrices (WQ², WK², WV²) that were learned independently. Each additional layer can detect higher-order relationships that earlier layers could not see.
Why does stacking layers help? Because each layer sees a richer input than the previous one. Layer 1 starts from raw embeddings — it can only detect relationships between the original token identities. Layer 2 starts from contextually-enriched vectors that already encode some relationships. Layer 2 can therefore detect more abstract patterns: not just ‘noun next to verb’ but ‘subject performing an action in a specific semantic domain.’ Later layers can detect even more abstract structures.
Real models stack 12, 24, 48, or 96 such layers. Each one adds a further round of contextual refinement. By the final layer, the vector for each token is a deeply enriched representation that reflects its meaning in this specific sentence, informed by everything the model learned during training about language and the world.
5.9 Getting the Final Word Prediction
After all attention layers have run, we have one final contextual vector for each token. To predict the next word, we take only the last token’s vector — here, ‘sat’ after Layer 2. This vector carries the accumulated context of the entire sequence.
This vector is multiplied by the Language Model Head — a matrix of dimensions D×V. In our example, D=3 and V=5, so this is a 3×5 matrix with one column per vocabulary word. The multiplication produces V=5 raw scores, one per word in the vocabulary:
final vector for ‘sat’ (D=3) × LM Head (3×5) = 5 logits (one per word)
Softmax converts the 5 logits into probabilities summing to 1. In our sentence ‘The cat sat ___’, the correct next word is ‘on’. A well-trained model assigns it the highest probability:
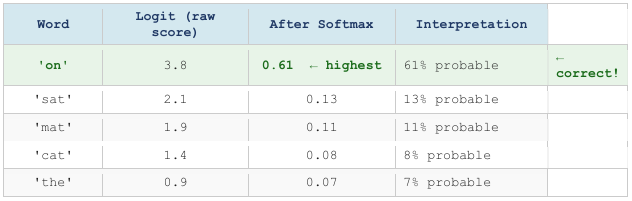
Table 8. Final word prediction. The model assigns 61% probability to ‘on’ as the next word after ‘The cat sat’. The language model head, which has one column per vocabulary word, projects the final contextual vector into a score for every word simultaneously.
The word ‘on’ is then appended to the sequence. The entire forward pass — embedding lookup, all attention layers, language model head — now runs again on four tokens: ‘The’, ‘cat’, ‘sat’, ‘on’. A new next word is predicted. This continues until the sentence is complete.
The full loop: embedding lookup → Layer 1 (Q¹K¹V¹) → Layer 2 (Q²K²V²) → … → Layer N → LM Head → softmax → one word. Append that word. Repeat. This is generation.
5.10 How Training Corrects the Model
At initialization, all matrices are random. The logits are random numbers. Softmax spreads probability roughly equally across all V words: about 1/V each, which is nearly zero. The correct word — ‘on’ — gets about 0.02% probability instead of 61%. The model is completely wrong.
The loss function measures this wrongness:
loss = − log( probability assigned to correct word )
At initialization: loss = −log(0.0002) ≈ 8.5 (very high)
After good training: loss = −log(0.61) ≈ 0.49 (low)
Backpropagation traces this error backward through every computation in the forward pass, computing how much each number in each matrix contributed to the wrong prediction. Every matrix — the LM head, then WV, WK, WQ at every layer, then the embedding rows — receives a gradient and is adjusted by a tiny step. Repeated trillions of times across the training corpus, random matrices become structured ones that reliably push probability mass toward correct words.
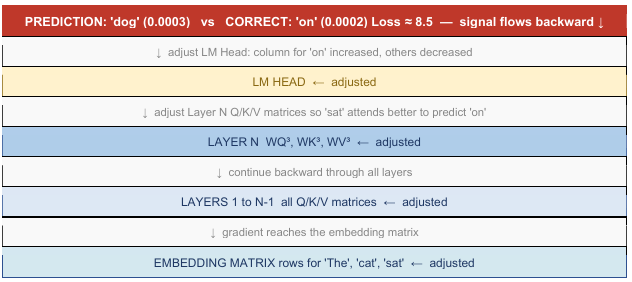
Figure 4. Backpropagation flows in reverse through the complete pipeline. Every matrix is adjusted by a gradient step. After trillions of such corrections across the training corpus, the initially random matrices develop structure that reliably produces correct predictions.
6. Fine-Tuning and RLHF: Building the Assistant
A pre-trained base model is a powerful text predictor but a poor assistant. Asked a question, it may continue the text as if writing an exam. The gap between ‘text predictor’ and ‘helpful assistant’ is closed by two additional training stages.
6.1 Supervised Fine-Tuning (SFT)
SFT takes the pre-trained model and continues training it on a curated dataset of (prompt, ideal response) pairs written by human annotators. The same backpropagation process runs, but instead of raw text, it trains on demonstrations of helpful, clear, honest responses. The pre training knowledge is not erased; SFT shifts the model’s statistical tendencies toward the desired assistant style. Think of a doctor who has always written clinical notes learning to explain conditions in plain language — the knowledge is unchanged, the communication style is retrained.
SFT does not teach the model new knowledge. It teaches it a new style of using the knowledge it already has.
6.2 Reinforcement Learning from Human Feedback (RLHF)
The Core Insight
It is easier for humans to compare two responses and say which is better than to write an ideal response from scratch. RLHF exploits this asymmetry. It collects comparison judgments at scale and uses them to train a reward model — a learned proxy for human preferences — which then guides further training of the main model.
The Four Steps
- Collect comparison data. For many prompts, the model generates multiple candidate responses. Human annotators indicate which is better. This captures nuanced preferences that are easy to recognize but hard to articulate explicitly.
- Train a reward model. A separate neural network is trained to predict a scalar preference score for any prompt-response pair. This extends human judgment to unlimited new responses.
- Optimize via PPO. The main model generates responses; the reward model scores them; parameters are adjusted to make high-reward responses more probable. A KL divergence penalty prevents the model drifting so far that it finds degenerate ways to score highly.
- Iterate. New comparison data is collected on the improved model. The reward model is updated. The cycle repeats.
What RLHF Changes and Why It Matters
RLHF adjusts which patterns the model accesses and how it combines them. Helpful, well structured, appropriately hedged responses consistently receive higher reward scores and therefore consistently stronger parameter updates in their direction. Over many iterations, helpfulness, honesty, and warmth become stable structural tendencies — encoded in the weights, not in the context window.
This is why post-training personality is structural and persistent. It was built into the weights by the same backpropagation mechanism used in pre-training, just with different training signal. You cannot prompt it away — you would need to retrain to change it.
Modern Variants
Constitutional AI (CAI) uses a set of explicit principles to guide model self-critique, generating synthetic preference data at scale. Reinforcement Learning from AI Feedback (RLAIF) uses a separate AI model as the annotator instead of humans, enabling much larger scale. Both share the same structural logic as RLHF.
7. The Constraint Problem
7.1 The Statistical Blend
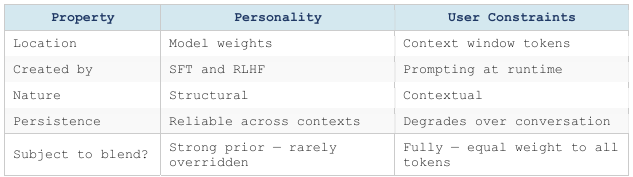
At each generation step, the model performs one operation: it blends all information in the context window, weighted by attention, to predict the most likely next token. There is no priority mechanism. There is no hierarchy. Everything competes equally in the attention-weighted blend. When a user provides an explicit constraint — ‘always respond formally’ or ‘never mention competitor products’ — that constraint exists as tokens in the context window. It participates in the blend on equal footing with conversational momentum, trained personality, pre-training patterns, and the current prompt. It wins or loses based on attention weights. It has no special status.
LLMs optimize for the most likely next token, not the most constrained next token. When explicit instructions, implicit assumptions, safety policies, and learned patterns conflict, the model does not reason about hierarchy — it statistically blends them.
7.2 Why Personality Persists But Constraints Do Not
Personality was built into the weights through SFT and RLHF. It is structural — part of what the model is. User constraints live in the context window as tokens. They are contextual and fade.
7.3 The Apology Pattern
When a user points out that their constraint was violated, the model typically apologizes. This apology is not remorse. It is pattern completion. The training corpus contains vast amounts of text in which apologies follow accusations of wrongdoing. ‘You ignored my instruction’ is followed, statistically, by an apology. The model has no access to what it did or why. It produces the most likely continuation of the current context.
7.4 Why Mitigations Fall Short
Common strategies share a fundamental limitation: they operate at execution time in the same token space subject to blending.
- Better prompting: more prominent constraint tokens, but still no priority mechanism.
- Repeated injection: constraint at every step, still blended equally with everything else.
- RAG for constraints: more tokens representing the constraint, but knowing is not enforcing.
- Output verifiers: external filtering after generation, not shaping of generation itself.
- Fine-tuning: moves constraints toward the weights, stronger but still probabilistic.
The constraint problem is architectural, not incidental. The blending mechanism that makes LLMs extraordinarily powerful at capturing the nuance of human language is precisely the mechanism that prevents them from enforcing hard constraints reliably.
8. Conclusion
Large language models work by learning a geometric space where meaning is encoded as position, and navigating that space one token at a time. The embedding matrix provides starting positions. The Query, Key, and Value matrices — learned independently at every attention layer — compute contextual relationships through dot products, softmax weights, and weighted Value sums. Each layer refines the representations further. The language model head projects the final vector across the entire vocabulary simultaneously, producing a probability distribution. A word is sampled. The process repeats. All matrices start as random noise. Training corrects them through backpropagation: the error between predicted and correct words flows backward through every matrix in every layer, nudging each parameter slightly in the direction that reduces the error. Repeated trillions of times, this produces the structured, knowledge-rich geometry that makes language models work. Fine tuning and RLHF then shape the resulting base model into a helpful assistant whose personality is structural — encoded in the weights — and therefore persistent. The constraint problem is the structural limitation that follows. Constraints provided at runtime enter the context window as tokens and participate in the attention-weighted blend with no priority over anything else. They are contextual, not structural. Personality is structural and persists. Closing this gap requires working at the level of training and architecture — not at the level of the prompt.